Why Choose One: Multi-Engine Analytics with Apache Wayang

summary
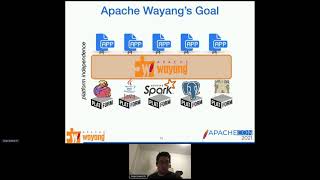
Apache Wayang decouples platform-agnostic plans from execution and maps Java/Scala/Python/SQL operators to Spark, Flink, JDBC and ML backends using an inflator + enumerator + cost-based optimizer with pruning and runtime re-optimization. Benchmarks show a mixed Spark+Java SGD pipeline runs about one order of magnitude faster than single-engine runs; TPC-H joins split between Postgres and Spark via a channel conversion graph for minimal data movement. The project is an Apache TLP (Nov 2025) with 9 PMC, 18 committers and 58 contributors and uses profiling to learn operator cost parameters.
AI-written summary · about
chapters (6)
- 0:00Introduction to multi-engine analytics
- 4:05Problem of engine selection
- 13:15How Apache Wayang works
- 24:27Query optimizer details
- 33:03Project origin and future
- 38:29Q&A session
related talks
 54mApache Wayang: Bringing Big Data to the IoT
 42mApache Spark on planet scale
 50mA Java Implementer's Guide to Better Apache Spark Performance
 21mAvoiding Spark Pitfalls at Scale
 46mSpark: One Tool for Everything?
 41mPython, Java, or Go: It's Your Choice ...
 52mSolving Analytical Problems using Apache Spark
 36mNo more struggles with Apache Spark (PySpark) workloads in production