Migrate Data, Mesh in mind

summary
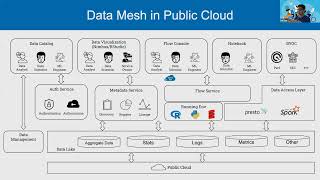
A migration replaces an on‑prem Hadoop warehouse with a cloud pipeline that actually runs: Kafka topics → DataHub data‑sync writing Avro→Delta into S3 → Databricks tables, with transformations by dbt on Airflow via Kubernetes spot operator (dbt artifacts built into Docker images). Key problems are legacy pipes that silently lost rows, manual copying of old Hadoop data, schema breakages that dropped a critical field and skewed SLAs (costly), and domain teams needing onboarding; outcome: domain‑owned pipelines and dbt tests improve quality but federated governance and cost control remain unfinished.
AI-written summary · about
chapters (4)
related talks
 31mA Journey of Migrating Data Platform from Data Center to Cloud
 26mEffective Data Migration: Challenges & Success
 42mWeb Development To Big Data. A Journey
 21mSnowflake and dbt -- Our Journey to the Cloud
 31mOne Data Pipeline to Rule Them All
 39mUsing Streaming Data Pipelines in the Cloud to Achieve Success
 42mBillion-Scale Triumph: Innovating at the Edge of Cloud Data
 01h 03mDiscovering the value of a cloud data platform